20 years of experience, for what it’s worth, and a vehemently disagree. But to extend an olive branch, I think a big reason for the seemingly polar opposite reception of LLM coding online is the context.
If you give an LLM all the tools it needs to write, research and verify it’s code, to test the result (for example, in a browser), give it access to all the context it needs, like documentation, use it for code that is new, but not largely novel (CRUD business app vs. invent a new algorithm) and a competent person uses it, it’s genuinely great. Great in a way no sane person could deny.
Inversely, if you’re working in a shitty environment already, without documentation, where everything exists as implicit knowledge in peoples heads, where you can’t test and develop freely, where you’re forced to use shit LLMs or “hardened” aka shitty tools, for a extremely uncommon domain, you might have worse experiences.
This is really more a case of possibility #2. Specifically, why are you rolling your own in the first place? The whole reason the output of the AI is “probably flawless”, is because this operation already has a million implementations. What’s the value in conjuring up another one and adding it to the code that needs to be maintained? Yeah, binary trees aren’t terribly complicated, but neither is struct Vector3 { floatx, y, z; }; or any of its operations, until you realise you’ll be running those operations an awfully lot, so it would be better if it had the right alignment and SIMD instructions were used in its operations, and of course, if you have Vector3 you’ll probably also need a Matrix4x3 and a Quaternion etc., so in the end it’s just better to use an existing solution.
This is what I mean with turning good devs into mediocre ones: the worst solution becomes the easiest solution, so that’s what people will lean towards.
Of course, there can also be situations like you have a very specific use-case and using something off-the-shelf would be sub-optimal, or you’re working with old code and making their own was the decision the previous person or your dumbass past-self made, so that’s just what you have to work with. But the AI is going to struggle more with those cases too.
Lastly, I also mentioned “energy”. If you’re trying to put in words things that aren’t easily conveyed in English (or any other natural language) all the time, you burn through your cognitive endurance like crazy. This is why you don’t want to be in a highly technical meeting in the morning, so being in one all day with a moron you can’t really come to common understanding with (beyond the size of its context window) is even worse.

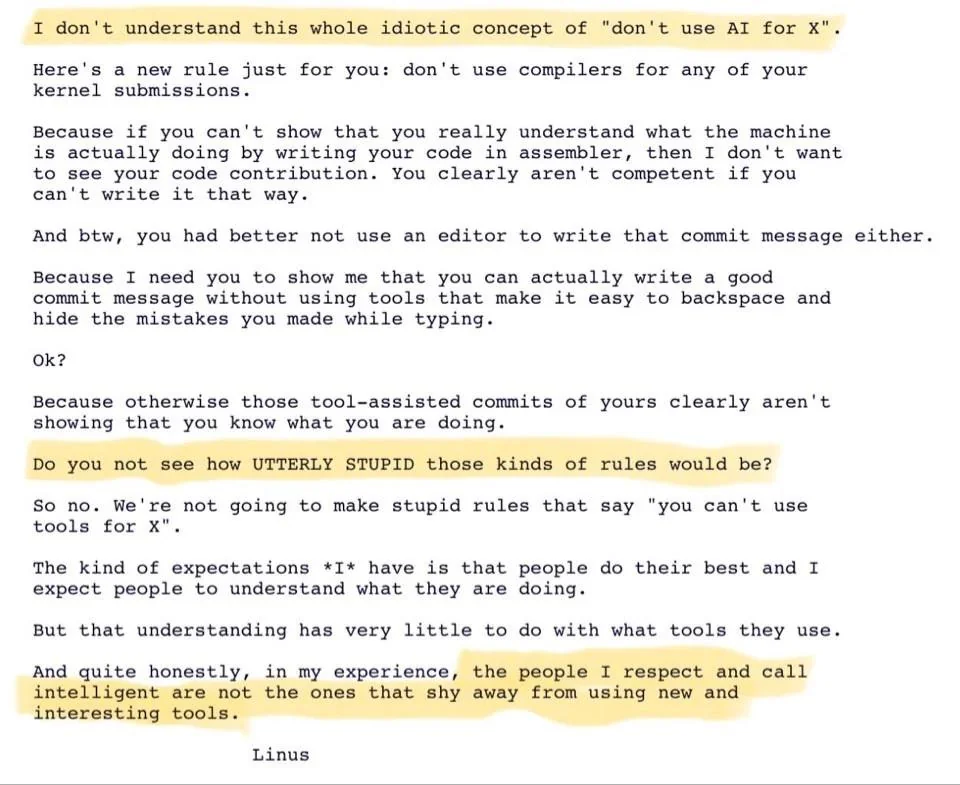
Shitty devs will write shitty code using AI
Good devs will write good code faster with AI
I have for sure seen far worse hand written code than AI would produce
If it takes less time and energy to describe what you want in natural language than to just write the code, there are two possibilities:
In the end, only shitty devs benefit, while being prevented from becoming good devs, while good devs turn into mediocre devs.
20 years of experience, for what it’s worth, and a vehemently disagree. But to extend an olive branch, I think a big reason for the seemingly polar opposite reception of LLM coding online is the context.
If you give an LLM all the tools it needs to write, research and verify it’s code, to test the result (for example, in a browser), give it access to all the context it needs, like documentation, use it for code that is new, but not largely novel (CRUD business app vs. invent a new algorithm) and a competent person uses it, it’s genuinely great. Great in a way no sane person could deny.
Inversely, if you’re working in a shitty environment already, without documentation, where everything exists as implicit knowledge in peoples heads, where you can’t test and develop freely, where you’re forced to use shit LLMs or “hardened” aka shitty tools, for a extremely uncommon domain, you might have worse experiences.
“I want a method that inverts a binary tree”
Can you code that quicker than you can describe it in natural language?
No obviously not, AI could give that to you in ~30 seconds.
And it would probably be flawless, but you can review it yourself to double check
This is really more a case of possibility #2. Specifically, why are you rolling your own in the first place? The whole reason the output of the AI is “probably flawless”, is because this operation already has a million implementations. What’s the value in conjuring up another one and adding it to the code that needs to be maintained? Yeah, binary trees aren’t terribly complicated, but neither is
struct Vector3 { float x, y, z; };or any of its operations, until you realise you’ll be running those operations an awfully lot, so it would be better if it had the right alignment and SIMD instructions were used in its operations, and of course, if you haveVector3you’ll probably also need aMatrix4x3and aQuaternionetc., so in the end it’s just better to use an existing solution.This is what I mean with turning good devs into mediocre ones: the worst solution becomes the easiest solution, so that’s what people will lean towards.
Of course, there can also be situations like you have a very specific use-case and using something off-the-shelf would be sub-optimal, or you’re working with old code and making their own was the decision the previous person or your dumbass past-self made, so that’s just what you have to work with. But the AI is going to struggle more with those cases too.
Lastly, I also mentioned “energy”. If you’re trying to put in words things that aren’t easily conveyed in English (or any other natural language) all the time, you burn through your cognitive endurance like crazy. This is why you don’t want to be in a highly technical meeting in the morning, so being in one all day with a moron you can’t really come to common understanding with (beyond the size of its context window) is even worse.