- 21 Posts
- 32 Comments
Joined 3 months ago
Cake day: July 29th, 2026
You are not logged in. If you use a Fediverse account that is able to follow users, you can follow this user.


 1·2 days ago
I didn’t write down my exact tokens/s in llama.cpp before installing the unlocker, but the numbers I got after were roughly the same as I remembered, which also makes sense since I use quantized models that afaik use integer tensor ops.
token generation is bottlenecked by memory speed not compute power. your prompt processing/prefill speeds might’ve gone up
 2·4 days ago
https://piefed.social/comment/13343280
PieFed has the concept of silencing another instance. A silenced instance is not defederated from but their posts do not show in the Popular or All feeds and their communities are not shown during onboarding. Their communities can still be found in the communities list (if you unblock the instance first) and joined in the normal way. Once joined, posts in there show up in the Subscribed feed of the joiner as usual.
Since I added silencing functionality I feel like there’s almost no need for (more) defederation. I can offer protection to newbies who don’t yet know which places to avoid and they can explore the dark corners when they’re ready. It’s a low-drama way to put a bit of distance between groups that rub each other the wrong way.
Yeah default blocks or silencing or something like that
PieFed allows admins different levels of blocking instances, they can do defederation but there are levels softer than that
oh yea feddit blocks shitjustworks https://feddit.online/instance/sh.itjust.works/posts
maybe @xSikes@feddit.online could ask their admins to convert the defederation to a “silenced” or whatever that feature is on PieFed
32GB RAM, RTX 2080 8GB VRAM, I use Tiel Coder 35b-a3b (it’s a fine tune of Qwen 3.6) with Zoo Code
I see the last activity was 2 months ago.
that means no one from your instance is subscribed, if you subscribe then you’ll get new posts
you can see that there are new posts here https://sh.itjust.works/c/localllama
Well it’s a MoE, so at least in llama.cpp you can offload some experts and use the new MoE caching
--moe-cache-miband you’ll probably still get at least 90% of the speed
Unsloth has their Q4 quant at 506 GB 💀
Active parameters aren’t that high, you’ll need KV cache in VRAM too, so maybe it would run in 64GB VRAM

I’m excited to test it. Maybe next time I need to do some coding, unless maybe Qwen 4 is out by then!

Yeah someone said they’re way better at 3d modeling, but how do we know the closed models aren’t actually 5 separate models in a trenchcoat? Behind the scenes they could be making tool calls to each other, or they could have a small router model that decides which model to send each request to. They could literally have 100 different fine-tunes to choose from dynamically and we would still think it’s all a single model that’s just really good at everything. (100 is unlikely, just an example)

I haven’t gotten to try it yet
I cap mine to 80k (Q8_0) just cause it seems to be enough for agentic coding (Zoo Code), and past 80k the speed and quality start to drop
Yes they’re based on Qwen. Ornith 1.5 is a fine-tune of Qwen.
Tiel Coder is based on Ornith 1.5, it’s technically just a quant and an improved template, but it seems like an improvement for people who are going to use Q4 anyways.
Yeah RTX 2080 8GB and 32GB of system RAM, I wrote a guide
https://lemmus.org/post/24235317
I’ll have to do an updated guide once Llama.cpp v0.7.0 comes out because there’s a new option now for MoE expert caching. It doesn’t work that well yet but I think they’ll continue to improve it. https://lemmus.org/post/25955310
But is it actually better than Ornith or Tiel 35b-a3b?
I’m looking at around 30-50k context until I start running out of room.
I can do 80k+ just fine with 35b-a3b. I don’t think 50k would be enough for agentic coding.
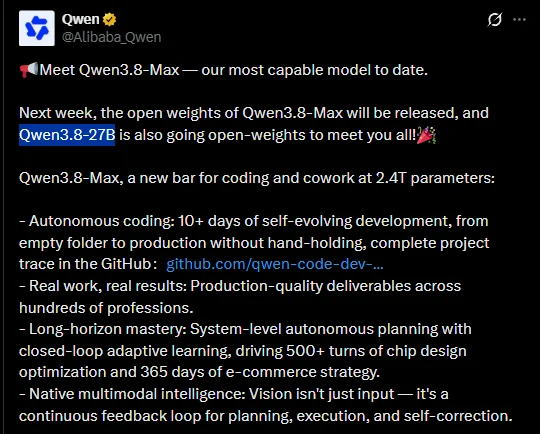
maybe it’s better than Qwen 3.6 35b a3b?
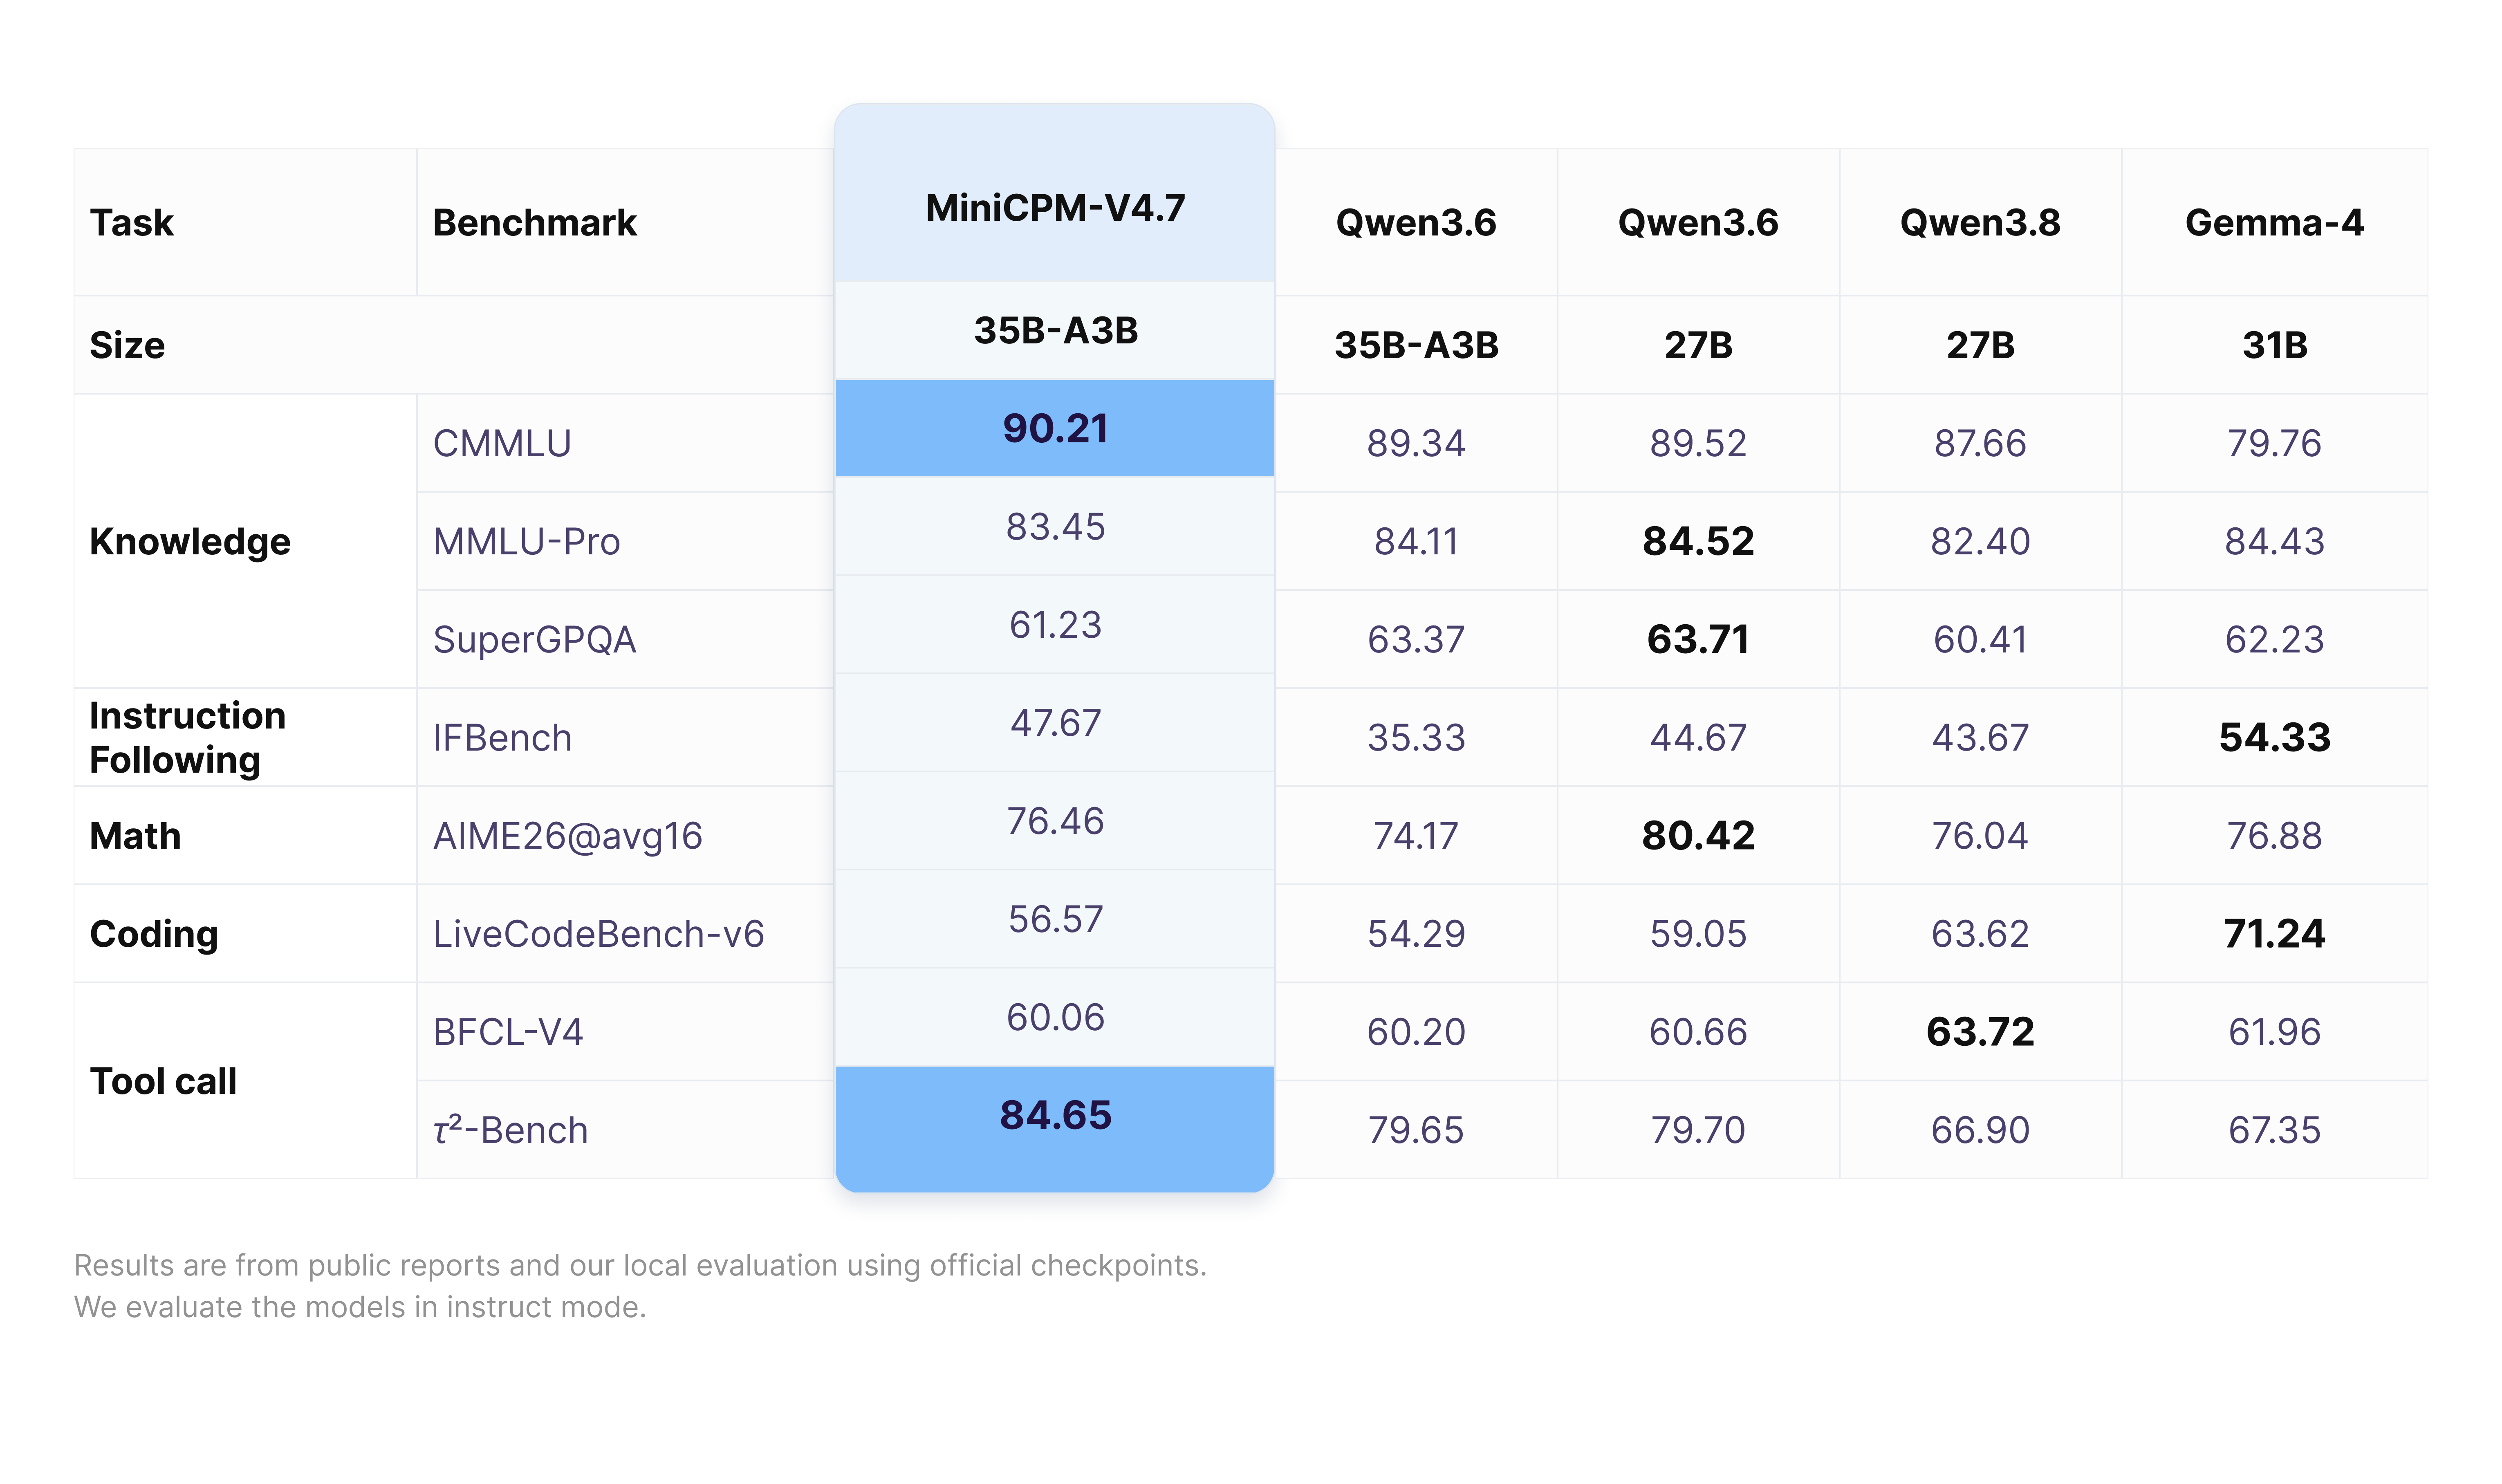

If they can make the KV cache size scale more efficiently with many tokens, like DeepSeek 4.1 Flash fitting 1 million tokens in 890MB, it might give them enough room to add a couple billion parameters of weights and still fit well in 32GB GPUs
Yeah it’s a really nice size for older gaming computers. Of course it can still be beaten by smaller models from other labs, so that kinda defeats the purpose, but it’s nice in theory




yea I would guess LoRA training uses bf16